The Help Desk Ticket That Never Closes
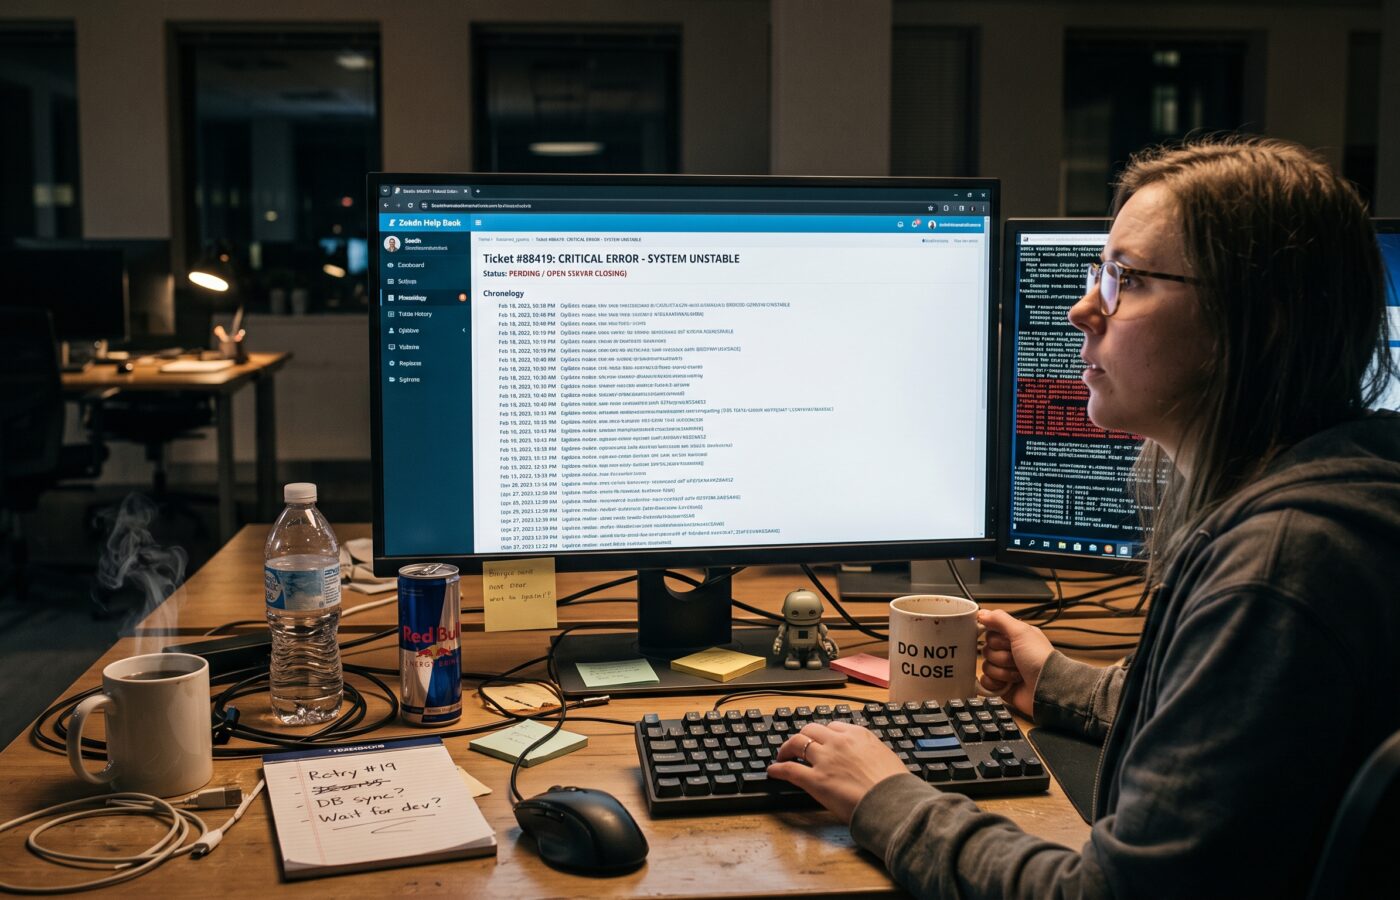
I still remember the ticket. Not because it was complicated, but because it refused to die. A user couldn’t print. We reset her printer queue and closed the ticket. Three days later, same user, same printer, same problem. We reinstalled the driver and closed it again. Two weeks after that, it came back a third time, and now it had spread to two more people on the same floor. Someone finally pulled the network switch logs and found a flaky port that had been dropping packets for a month. Three tickets, three technicians, three “resolutions,” and the real problem sat there the whole time waiting for someone to look past the symptom.
If you’ve worked a service desk for more than a year, you have your own version of this story. The same goes if you deliver IT services for a living. A ticket closes on paper long before anyone fixes the underlying issue. It comes back wearing a different ticket number, often assigned to a technician who has no idea it’s the third act of a play that started weeks earlier. Everyone treats it as new. Nobody connects the dots. And the dashboard still says resolution times look great.
Closing a Ticket Is Not the Same as Solving a Problem
Here’s a distinction that gets lost in a lot of help desk cultures: an incident and a problem are not the same thing.
What Counts as an Incident
An incident is the thing in front of you right now. The printer won’t print. The VPN dropped. Someone can’t log in. Your job in that moment is to restore service fast. Speed is genuinely the right thing to optimize for here.
What Counts as a Problem
A problem is the underlying cause that keeps generating incidents. Think of the flaky switch port, the expired certificate nobody rotated, or the onboarding script that silently fails for accounts created after a certain date. Problems don’t care how fast you closed the last ticket. They wait for the next trigger and then fire again.
Why ITIL Keeps Them Separate
ITIL treats incident and problem management as separate practices for a reason, and it’s not bureaucratic hair splitting. When a team measures only incident resolution speed, and never funds problem management as its own discipline, you get exactly the story I opened with. Technicians earn credit for clearing the queue, not for asking why the queue keeps refilling with the same issue in a new hat. Plenty of service desk leads privately admit they know certain tickets recur, but nobody carves out time for the deeper investigation. So the recurring issue becomes background noise, and everyone gets used to it. That normalization is the real danger, more than any single outage. Get this right and you build IT services that clients can actually rely on.
The Seven Ways a Ticket Fakes Its Own Death
Years of auditing IT services teams turn up the same handful of patterns whenever a ticket looks closed but isn’t.
Premature Closure
A technician applies a fix, the symptom disappears, and the ticket closes without anyone confirming the user experienced full resolution over time. A reboot that clears an error today doesn’t mean the memory leak causing it is gone.
The Workaround Dressed Up as a Fix
Clearing a cache, restarting a service, or manually correcting a data record all make a symptom disappear without touching whatever generated it. Workarounds have their place. They buy time during a crisis. But that only works if the technician logs the fix as a workaround and opens a companion problem record, and that second step often just never happens.
Vague Closing Notes
“Resolved” with nothing else written tells the next technician nothing when the issue resurfaces. I’ve opened ticket histories where every entry in a six month chain says some version of “fixed” with zero detail on what actually happened. That’s not documentation. That’s a shrug.
The Missing Problem Record
Most ticketing platforms don’t force a technician to link a third recurrence of an incident to a formal problem investigation. Without that nudge, most teams simply skip it, no matter how good their intentions are.
Automation That Misfires
Some platforms automatically reopen a ticket the instant a user replies to a closure notification, even if the reply just says “thanks.” I’ve seen reopen rates spike for no reason beyond polite users hitting reply. That’s a tooling problem pretending to be a service quality problem, and it deserves its own separate audit.
Ticket Ping Pong
A request bounces between two or three groups because nobody ever defined ownership clearly. Networking blames the application. The application team blames networking. Eventually whoever gets tired of arguing first closes the ticket, whether or not anyone actually fixed anything.
The User Who Gives Up
This one is the most human, and maybe the most worrying. A user stops escalating a recurring annoyance because reporting it hasn’t worked before, so they route around it or just tolerate it. Your ticket volume looks healthy. Your environment quietly degrades anyway. This pattern should worry executives most, because no dashboard you’re probably looking at will ever show it to you.
What the Benchmarks Actually Say
I like giving IT services clients a number to anchor on, because “reduce reopens” is vague and “get below 5 percent” is something a team can actually act on.
A Number Worth Anchoring On
Industry guidance generally treats a reopen rate under 5 percent as healthy. Anything consistently above 10 percent deserves a formal investigation into root causes rather than technician performance. When reopen rates climb, most organizations instinctively blame the individual technician. That’s usually the wrong diagnosis. It’s far more often a process gap, a missing knowledge base article, or a problem record nobody ever opened.
Why Reopen Rate Still Undercounts the Problem
Reopen rate as a metric can badly understate how much recurrence is actually happening, because plenty of frustrated users just file a brand new ticket instead of reopening the old one. If your system only tracks explicit reopens, you’re measuring a fraction of the real repeat volume. I always recommend pairing reopen rate with a search across ticket subjects and categories for recurring themes, not just recurring ticket IDs.
The Trouble With Worshiping MTTR
A lot of executive reporting treats mean time to resolution as gospel, and I understand why. It’s easy to chart and easy to compare month over month. But MTTR alone can reward exactly the behavior that causes all of this. A team under pressure to hit an aggressive MTTR target has every incentive to apply the fastest fix and close the ticket, even when that fix is a workaround, not a resolution. Pair MTTR with reopen rate and with a monthly count of problem records opened. If those second two numbers stay flat or fall while MTTR looks great, that’s a good sign. If MTTR looks great but reopens keep climbing, you’re not getting faster. You’re just getting better at hiding the same work under a new ticket number. That’s not what any IT services provider wants to be known for.
Building Problem Management as an Actual Practice
Most IT services organizations I walk into already have problem management written somewhere in their ITSM policy. Almost none of them practice it with any real rigor. There’s a big gap between documenting a process and actually running it under deadline pressure, and that gap is where all of this trouble lives.
Start With a Trigger Rule
Build a mechanical trigger rather than an optional one. Set a rule so that if an incident type recurs a set number of times in a defined window, say three times in thirty days, the system automatically flags it for problem investigation. Don’t rely on a technician noticing the pattern and volunteering extra work. Judgment calls get skipped when people are busy. Automatic triggers don’t skip anything.
Give the Problem Record a Real Owner
Once flagged, a problem record needs an owner who isn’t the same person racing to clear the incident queue. Organizations resist this step most, because it looks like adding headcount for something that never shows up as a closed ticket count. But someone measured on same day ticket closure will always deprioritize root cause analysis. The two incentives directly conflict, and no amount of good intentions fixes that on its own.
Build and Actually Use a Known Error Database
A known error database, or KEDB, isn’t documentation for its own sake. It turns “we’ve seen this before” into a two minute lookup instead of a rediscovery from scratch. I’ve watched senior technicians reinvent the same fix for the same issue three times in a single year. Nobody ever wrote it down anywhere the next person would think to check. That’s not a technology gap. It’s a habit gap, and a small amount of discipline fixes it.
Review Closed Tickets on a Schedule
Review closed tickets regularly, not just when something breaks badly enough to force attention. Run a monthly pass through your highest volume categories, your highest reopen rate categories, and any resolution notes full of workaround language. That single habit surfaces patterns no individual ticket will ever reveal on its own. It’s slow, unglamorous work. It’s also the entire difference between an IT services team that firefights forever and one that gets quieter over time.
Where Shift Left and Self Service Fit In
Clients of IT services providers often ask me about self service portals and knowledge bases. They assume these are separate from everything above. They aren’t. They’re the natural output of good problem management done well.
Turning Root Cause Work Into Self Service
Every properly closed problem record should produce something concrete: a knowledge base article, an updated runbook, or a self service fix that lets a user solve the issue without ever opening a ticket. People call this shifting left, meaning you push resolution capability as close to the user as the issue reasonably allows. This only works if real root cause work feeds the knowledge base, rather than generic vendor documentation nobody customized for your environment. I’ve seen knowledge bases full of articles that are technically complete and practically useless. They describe a generic version of the problem. They never capture the specific fix that works in your own IT services environment.
The Payoff of Doing This Well
Done well, this creates a genuinely useful cycle. Fewer repeat tickets free up time for the problem management work that prevents the next round of repeat tickets. Done poorly, you get a service desk that stays perpetually busy putting out the same three fires on rotation. The team feels overworked because ticket volume is high, when the real issue is low diversity behind that volume. That’s exactly the kind of compounding value clients expect when they pay for IT services.
What This Means If You’re Running IT Services for Clients
If you run an internal IT team, the ticket that never closes mostly drains productivity and morale. If you provide IT services to external clients, it becomes a trust and retention issue, and that distinction deserves its own attention.
Clients Notice Recurrence, Even Without the Vocabulary
Clients notice recurring problems even when they can’t name the ITSM concept behind them. They don’t say “your reopen rate is too high.” They say “we keep having the same problem” or “it feels like nothing ever actually gets fixed here.” That perception builds slowly and it’s genuinely hard to undo once it sets in, because clients usually stay quietly frustrated for months before they say anything out loud. The IT services providers who keep clients longest aren’t the ones with the fastest average response time. They’re the ones who can point to a falling trend in recurring issues for a given account, and who tell a client proactively: “we noticed this kept happening, so we changed the underlying configuration instead of just fixing it again.” Saying that before a client complains does more for the relationship than almost any other habit I coach.
Rethinking How You Structure SLAs
This should also change how you write contracts and SLAs. An SLA built entirely around response time and resolution time gives zero credit for problem prevention. It can even penalize a technician for spending an extra twenty minutes doing it right instead of closing fast. If you’re structuring IT services agreements, build in a measure for problem management activity. Track recurring issue reduction too, not just speed. Otherwise you’re paying for exactly the behavior you don’t want.
A Closing Thought
Whether you run an internal help desk or deliver IT services to outside clients, the same principle applies. None of this is really about tickets. It’s about what an organization chooses to reward. If leaders only measure and celebrate how fast a queue empties, that’s what they’ll get: technicians who excel at making problems look solved. If leaders instead build in room, staffing, and genuine credit for figuring out why something keeps happening, they’ll get an environment that actually calms down over time, instead of one that just gets faster at repeating itself.
The ticket that never closes isn’t a technology problem. It’s a signal. It’s telling you something true about your environment that a green dashboard is quietly hiding. In my experience, the consultants and teams who listen to that signal, instead of just clearing the queue, are the ones who build IT operations that clients trust for years, not months.
FAQ
What is a good ticket reopen rate for a help desk?
A reopen rate under 5 percent generally indicates strong resolution quality, while anything consistently above 10 percent deserves a systematic investigation into root causes rather than individual technician performance. See Giva’s breakdown of reopen rate causes and benchmarks.
What’s the actual difference between incident management and problem management?
An incident is a single unplanned event that causes a service disruption, and the goal is fast restoration. A problem is the underlying cause of one or more incidents, and the goal is prevention through root cause analysis. Treating them as the same practice is a common source of recurring issues. See Atlassian’s comparison of incident and problem management.
Why does problem management get neglected even when it’s part of official policy?
Incident management delivers visible, immediate results, while problem management is slower investigative work that happens after the pressure is off. Without ownership separate from incident response, it consistently loses out to whatever feels urgent that day. See ITSM.tools on why problem management is often overlooked.
Should IT teams track mean time to resolution or reopen rate?
Track both, and never rely on just one. MTTR alone can reward fast workarounds over durable fixes. Pairing it with reopen rate and the number of problem records opened each month gives a far more honest picture of whether tickets are actually getting solved or just cycled. See InvGate’s guide to service desk KPIs.
What is a known error database and why does it matter?
A known error database, or KEDB, is a maintained record of identified problems, their root causes, and available workarounds or fixes. It turns rediscovering a known issue into a quick lookup instead of repeated troubleshooting from scratch, and it’s a core deliverable of mature problem management practice. See ManageEngine’s explanation of ITIL incident, problem, and change management.
What should an IT services provider prioritize to reduce ticket recurrence?
An IT services provider should prioritize funding problem management as its own discipline, not just fast incident response. Tracking reopen rate and the number of problem records opened each month shows whether IT services delivery is actually improving over time. See ITSM.tools on common IT help desk issues and fixes.
References
- Giva. “Help Desk Ticket Reopen Rate: Causes & Fixes.” https://www.givainc.com/blog/ticket-reopen-rate-causes/
- Atlassian. “Problem Management vs. Incident Management.” https://www.atlassian.com/incident-management/devops/incident-vs-problem-management
- ITSM.tools. “Incident vs Problem Management: Key Differences, Roles, and Best Practices.” https://itsm.tools/incident-vs-problem-management/
- InvGate. “Help Desk Metrics and Service Desk KPIs: What to Track and Why It Matters.” https://blog.invgate.com/service-desk-kpi
- ManageEngine. “Difference Between ITIL Incident, Problem, Change, and Asset Management.” https://www.manageengine.com/products/service-desk/itsm/incident-problem-change-asset-management.html
- ConnectWise. “Incident vs. Problem Management.” https://www.connectwise.com/blog/incident-vs-problem-management
- ITSM.tools. “10 Common IT Help Desk Issues and How IT Support Fixes Them.” https://itsm.tools/common-it-help-desk-issues-and-fixes/